A Google News scraper in Python starts with a choice of surface. RSS feeds cover lightweight monitoring, Google Search with tbm=nws covers keyword tracking, and a dedicated Google News API covers high-volume collection with proxies and parsing handled on the service side. We ran all three against the same 30 queries on the same day, and the comparison section below puts numbers on what each returns.
What Google News Offers a Scraper
Google News is an aggregator, and that is what makes it worth scraping. One surface carries headlines from tens of thousands of publishers, already deduplicated into stories, grouped by topic, and localized by country and language. Scraping a single news site gets you that site. Scraping Google News gets you coverage, which outlets picked a story up, how fast, and under which headline. That feeds brand monitoring, competitor tracking, trend detection, and dataset building, and the pipelines at the end of this guide turn two of those into code.
Per article, the available fields are the headline, snippet, link, publication timestamp, publisher name and URL, and thumbnail. Full article text is not in any of the feeds, and the Google News API section below shows how to fetch it separately.
Does Google Have an Official News API?
No. Google deprecated its official News API back in 2011 and shut it down for good, so every “Google News API” on the market today is a third-party service backed by scraping, ours included. The only official machine-readable surface that remains is the RSS layer, which is why it opens the list of methods.
Setup and Prerequisites
Ensure you have a Python environment with the following libraries:
pip install requests feedparser pandas
# Optional: For sentiment analysis and visualization later
pip install nltk matplotlib
Everything below runs on stock Python plus these packages.
Extracting Structured Data from Google News RSS Feed
Google serves the News RSS feeds deliberately, but their URL structure is undocumented and can change without notice. The method fits lightweight, real-time monitoring without heavy dependencies.
To get a feed, insert /rss into the standard URL path. The topic page
https://news.google.com/topics/CAAqIAgKIhpDQkFTRFFvSEwyMHZNRzFyZWhJQ1pXNG9BQVABbecomes
https://news.google.com/rss/topics/CAAqIAgKIhpDQkFTRFFvSEwyMHZNRzFyZWhJQ1pXNG9BQVABBe aware that XML feeds may occasionally lack complete metadata or encounter rate limits during high-volume fetching. Since URL structures change without notice, ensure your parser includes error handling.
Four main endpoints:
| Type | URL Format | Description |
|---|---|---|
| Top news | https://news.google.com/rss | Main news feed, optionally filtered by language and region |
| By topic | https://news.google.com/rss/topics/<TOPIC_ID> | News for a specific topic (requires topic ID) |
| By topic section | https://news.google.com/rss/topics/<TOPIC_ID>/sections/<SECTION_ID> | News for a specific section within a topic (requires section ID) |
| Search | https://news.google.com/rss/search?q=<QUERY> | RSS feed for custom keyword search, supports modifiers like site:, when: |
Search feed parameters:
| Parameter | Example | Description |
|---|---|---|
| q | q=site:bbc.com when:1d | Search query for keywords, phrases, site filters, or time modifiers |
| hl | hl=en-US | Interface language (controls localization of results) |
| gl | gl=US | Geographical region (country code for results) |
| ceid | ceid=US:en | Country and language code for content feed, usually matches hl and gl |
Modifiers:
| Modifier | Example | Description |
|---|---|---|
| site: | site:bbc.com | Limit search to a specific website or domain |
| when: | when:1d | Restrict results to a time range (1h, 12h, 1d, 7d) |
| -word | -rumor | Exclude a word from results |
| ”phrase" | "new release” | Exact match for a phrase |
| OR | apple OR samsung | Logical OR between terms |
To scrape Google News via RSS:
- Create a script to generate the RSS URL with the desired parameters.
- Parse the XML from the feed. It’s best to use a specialized library like
feedparserfor handling RSS feeds.
Here’s a small Python example to generate a search-based RSS feed URL:
import urllib.parse


# Base parameters
base_url = "https://news.google.com/rss/search"
hl = "en-US"
gl = "US"
ceid = "US:en"


# Search modifiers
keyword = "technology"
site_filter = "site:bbc.com"
time_filter = "when:1d"   # when:1h, when:12h, when:1d, when:7d
exclude_word = "-rumor"
exact_phrase = ""         # e.g. '"new release"', every extra modifier narrows the feed

query_parts = [
    keyword,
    site_filter,
    time_filter,
    exclude_word,
    exact_phrase
]

query = " ".join(part for part in query_parts if part)

encoded_query = urllib.parse.quote(query)
encoded_ceid = urllib.parse.quote(ceid)

rss_url = f"{base_url}?q={encoded_query}&hl={hl}&gl={gl}&ceid={encoded_ceid}"

print(rss_url)
The second half consumes rss_url from the block above and refuses to fail silently, which the URL-structure warning earlier makes mandatory:
import feedparser

feed = feedparser.parse(rss_url)  # rss_url comes from the block above

if feed.bozo:
    raise SystemExit(f"Feed failed to parse: {feed.bozo_exception}")

items = []
for entry in feed.entries:
    items.append({
        "title": entry.get("title", ""),
        "link": entry.get("link", ""),
        "pubDate": entry.get("published", ""),
        "source": entry.get("source", {}).get("title", "") if entry.get("source") else "",
        "description": entry.get("description", "")
    })

if not items:
    print("Feed parsed but returned no entries, check the query and ceid")
Modifiers multiply, and each one narrows the feed. The stack technology site:bbc.com when:1d -rumor "new release" returns zero items, while dropping the exact phrase brings back a full feed of 100. Start broad and add one modifier at a time.
A working Streamlit wrapper is publicly available for practical use and can be adapted for custom projects:

The wrapper builds the same URLs this section walks through and exports the parsed feed.
Why RSS Beats the Other Two Methods
Google News RSS is server-rendered XML that Google publishes on purpose. There is no JavaScript to execute, no CSS classes that shift between page builds, no cookie walls, and no CAPTCHA, which are the failure modes that dominate HTML scraping. IP-level refusals exist but stay rare at polite volumes, our own 30-query pass hit exactly one. feedparser and a dozen lines of Python replace a headless browser. The ceiling is concrete too. A feed caps out at about 100 items, search feeds accept keywords and modifiers but no pagination, and metadata occasionally arrives incomplete. For monitoring a known set of topics or queries, RSS does the job with the least code and the fewest failure modes, and the measured comparison below shows what it trades away.
Scraping News Results from Google Search (Using tbm=nws)
The tbm=nws parameter filters standard Google Search results down to news items only. Google has been moving Search toward udm= parameters, but tbm=nws still returns the news vertical, and the requests below run against it. This method covers keyword trends and coverage that the feeds miss.

Three approaches reach this surface. Headless browsers (Selenium or Playwright) are flexible but resource-heavy and need constant upkeep as bot checks change. LLM-assisted browsing (Crawl4AI and similar) abstracts the selector handling but scales poorly on cost and latency. SERP APIs run IP rotation and HTML parsing server-side, which is where production setups end up.
This script uses HasData’s Google SERP API to extract structured CSV/JSON data immediately. Retrieve your API Key from the HasData dashboard.
import requests
import json
import csv


# Set up HasData’s Google SERP API endpoint and query parameters
url = "https://api.hasdata.com/scrape/google/serp"
params = {
    "q": "technology",  # search keyword
    "location": "Austin,Texas,United States",  # geolocation for search
    "tbm": "nws",  # news search mode
    "deviceType": "desktop",  # emulate desktop browser
}


# API headers with your HasData API key
headers = {
    "Content-Type": "application/json",
    "x-api-key": "HASDATA-API-KEY"
}


# Send request and parse JSON response
response = requests.get(url, params=params, headers=headers)
data = response.json()


news_items = []


# Extract relevant fields from each news result
for item in data.get("newsResults", []):
    news_items.append({
        "position": item.get("position"),
        "title": item.get("title"),
        "link": item.get("link"),
        "source": item.get("source"),
        "snippet": item.get("snippet"),
        "date": item.get("date"),
        "thumbnail": item.get("thumbnail")
    })


# Save results to JSON
with open("news.json", "w", encoding="utf-8") as f:
    json.dump(news_items, f, ensure_ascii=False, indent=2)


# Define CSV fields
csv_fields = ["position", "title", "link", "source", "snippet", "date", "thumbnail"]


# Save results to CSV
with open("news.csv", "w", newline="", encoding="utf-8") as f:
    writer = csv.DictWriter(f, fieldnames=csv_fields)
    writer.writeheader()
    writer.writerows(news_items)
Google limits results to 10 per page. To paginate through results, iterate requests by incrementing the start parameter (e.g., start=10, start=20) in your API requests.

The full Google News scraper code and a live Streamlit demo are available, so you can try it instantly or fork the project and adapt it to your own workflow.
Google News API (Topics and Trends)
HasData’s Google News API filters by topic, section, or location without the parsing overhead of generic search results.
Scraping Top Stories
The “Top Stories” section is the default feed displayed on the Google News homepage.

To collect data from this specific feed using HasData’s API, you must provide its unique identifier, the topicToken.
import requests
import json
import pandas as pd

API_KEY = "HASDATA-API-KEY"

# Google News API endpoint and topicToken for specific section
url = "https://api.hasdata.com/scrape/google/news"
params = {
    "topicToken": "CAAqJggKIiBDQkFTRWdvSUwyMHZNRFZxYUdjU0FtVnVHZ0pWVXlnQVAB"  # Top Stories
}

# Headers including API key
headers = {
    "Content-Type": "application/json",
    "x-api-key": API_KEY
}

# Request data from API
response = requests.get(url, params=params, headers=headers)

if response.status_code == 200:
    data = response.json()

    # Save raw JSON response
    with open("news.json", "w", encoding="utf-8") as f:
        json.dump(data, f, indent=2, ensure_ascii=False)

    news = data.get("newsResults", [])
    clean_rows = []

    # Extract and structure relevant fields for each news item
    for item in news:
        h = item.get("highlight", {})
        source = h.get("source", {})

        row = {
            "position": item.get("position"),
            "title": h.get("title"),
            "link": h.get("link"),
            "date": h.get("date"),
            "thumbnail": h.get("thumbnail"),
            "thumbnailSmall": h.get("thumbnailSmall"),
            "source_name": source.get("name"),
            "source_icon": source.get("icon"),
            "source_authors": ", ".join(source.get("authors", [])),
            "stories": json.dumps(item.get("stories", []), ensure_ascii=False)
        }

        clean_rows.append(row)

    # Convert structured data to CSV
    df = pd.DataFrame(clean_rows)
    df.to_csv("news.csv", index=False)
else:
    response.raise_for_status()
The API also supports keyword search, country, language, sort order, and other parameters listed in the official documentation. Keyword-search (q) responses return items flat, while token feeds nest each item under highlight, so match the parser to the request you make.
Scraping Specific Topics
To target niche verticals (e.g., Technology, Business), replace the topicToken in the script above.
Tokens for the standard categories:
| Category (Title) | topicToken |
|---|---|
| Top Stories | CAAqJggKIiBDQkFTRWdvSUwyMHZNRFZxYUdjU0FtVnVHZ0pWVXlnQVAB |
| U.S. | CAAqIggKIhxDQkFTRHdvSkwyMHZNRGxqTjNjd0VnSmxiaWdBUAE |
| World | CAAqJggKIiBDQkFTRWdvSUwyMHZNRGx1YlY4U0FtVnVHZ0pWVXlnQVAB |
| Local | CAAqHAgKIhZDQklTQ2pvSWJHOWpZV3hmZGpJb0FBUAE |
| Business | CAAqJggKIiBDQkFTRWdvSUwyMHZNRGx6TVdZU0FtVnVHZ0pWVXlnQVAB |
| Technology | CAAqJggKIiBDQkFTRWdvSUwyMHZNRGRqTVhZU0FtVnVHZ0pWVXlnQVAB |
| Entertainment | CAAqJggKIiBDQkFTRWdvSUwyMHZNREpxYW5RU0FtVnVHZ0pWVXlnQVAB |
| Sports | CAAqJggKIiBDQkFTRWdvSUwyMHZNRFp1ZEdvU0FtVnVHZ0pWVXlnQVAB |
| Science | CAAqJggKIiBDQkFTRWdvSUwyMHZNRFp0Y1RjU0FtVnVHZ0pWVXlnQVAB |
| Health | CAAqIQgKIhtDQkFTRGdvSUwyMHZNR3QwTlRFU0FtVnVLQUFQAQ |
A complete Google News API demo with all available parameters allows dynamic topic selection via a dropdown or custom value:

The dropdown covers the same tokens as the table above and accepts custom ones.
Scraping Full Article Content
The Google News API provides links, but not the full article text. To build a complete dataset, pass the extracted links to a Web Scraping API that handles JavaScript rendering and content extraction: fetch the link list from the News API, request each URL with outputFormat: ["markdown"], and save one file per article for RAG pipelines or analysis.
import requests
import json
import os

API_KEY = "HASDATA-API-KEY"

# Prepare parameters for Google News API request
params_raw = {
    "q": "",  # optional search query
    "gl": "us",  # geographic location
    "hl": "en",  # language
    "topicToken": "CAAqJggKIiBDQkFTRWdvSUwyMHZNRFZxYUdjU0FtVnVHZ0pWVXlnQVAB",
    "sectionToken": "",
    "publicationToken": "",
    "storyToken": "",
    "so": ""
}

# Remove empty parameters
params = {k: v for k, v in params_raw.items() if v}

news_url = "https://api.hasdata.com/scrape/google/news"
news_headers = {"Content-Type": "application/json", "x-api-key": API_KEY}

# Fetch news metadata from Google News API
resp = requests.get(news_url, params=params, headers=news_headers)
resp.raise_for_status()
data = resp.json()

# Extract links to full articles
news_links = [item.get("highlight", {}).get("link") for item in data.get("newsResults", []) if item.get("highlight", {}).get("link")]

web_url = "https://api.hasdata.com/scrape/web"
web_headers = {"Content-Type": "application/json", "x-api-key": API_KEY}

# Create folder to save markdown files
os.makedirs("news_md", exist_ok=True)

# Loop through each news link and scrape full article in Markdown
for idx, link in enumerate(news_links, start=1):
    payload = {
        "url": link,
        "proxyType": "datacenter",  # choose proxy type
        "proxyCountry": "US",       # set proxy country
        "jsRendering": True,        # enable JS rendering
        "outputFormat": ["markdown"]  # get content as Markdown
    }

    try:
        resp = requests.post(web_url, headers=web_headers, data=json.dumps(payload))
        resp.raise_for_status()
        md_content = resp.text
        filename = os.path.join("news_md", f"news_{idx}.md")
        with open(filename, "w", encoding="utf-8") as f:
            f.write(md_content)
        print(f"[{idx}/{len(news_links)}] Saved: {filename}")
    except Exception as e:
        print(f"[{idx}/{len(news_links)}] Error: {link} -> {e}")

print("All news saved in 'news_md' folder")
The loop reports progress as it saves files:

Each file lands as clean Markdown, ready for indexing or a retrieval pipeline.
How the Three Methods Compare
The three surfaces return measurably different data, so we measured it. We ran the same 30 queries (finance, tech, sports, entertainment, weather) through all three on the same day, one snapshot each of the RSS search feed, the first page of tbm=nws results through the SERP API, and the Google News API keyword search.
| RSS search feed | Search results (tbm=nws) | Google News API | |
|---|---|---|---|
| Articles per query (median) | 100 | 10 | 100 |
| Median article age | 22.5 h | 16.5 h | 23.4 h |
| Unique publishers per query (mean) | 65 | 9 | 67 |
| Empty results or errors | 1 of 30 | 0 of 30 | 0 of 30 |
The two feed-shaped surfaces nearly coincide. Averaged over all 30 queries, 89% of the smaller set’s headlines appeared in both the RSS feed and the News API (92% across the 29 queries where both returned data), and both drew on about the same pool of publishers (67 apiece on the queries both answered). What the API adds is not coverage but structure, parsed JSON fields with exact timestamps instead of XML you clean yourself, plus the topic, section, and story feeds that RSS only reaches through opaque tokens.
Search results through tbm=nws are a different surface altogether. One page carries ten results from about nine publishers, ranked and somewhat fresher (median age 16.5 hours against 22.5), and 95% of those headlines also exist in the News API’s hundred, so it behaves like a curated top layer rather than a collection channel.
Reliability separated nothing. The APIs returned all 30 queries, and one RSS request of 30 (climate change) failed outright, the request came back with an error instead of a feed, which is exactly the case the error handling in the RSS section exists for.
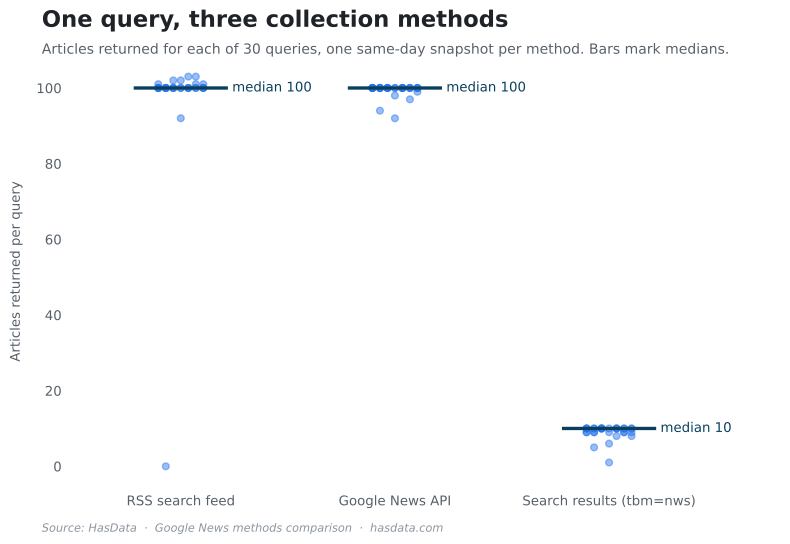
For monitoring a known query list, RSS returns a hundred items per query at zero cost. For the same breadth with the parsing already done, and for the topic feeds, use the News API. Scrape tbm=nws when you want Google’s ranking itself, ten curated results rather than a firehose.
From Headlines to Signals
Two pipelines below turn collected headlines into something you can act on. The first finds what the news is about, the second how it sounds.
Topic Frequency Analysis
This script identifies dominant narratives by tokenizing headlines, filtering out noise (stop words), and visualizing the top keywords.
Instead of hardcoding stop words, we use the standard list from nltk.corpus.
import requests
import json
from collections import Counter
import matplotlib.pyplot as plt
import nltk
from nltk.corpus import stopwords
import re

nltk.download('stopwords')

API_KEY = "HASDATA-API-KEY"

params_raw = {
    "q": "",
    "gl": "us",
    "hl": "en",
    "topicToken": "CAAqJggKIiBDQkFTRWdvSUwyMHZNRFp0Y1RjU0FtVnVHZ0pWVXlnQVAB",
    "sectionToken": "",
    "publicationToken": "",
    "storyToken": "",
    "so": ""
}

params = {k: v for k, v in params_raw.items() if v}

news_url = "https://api.hasdata.com/scrape/google/news"
news_headers = {"Content-Type": "application/json", "x-api-key": API_KEY}

resp = requests.get(news_url, params=params, headers=news_headers)
resp.raise_for_status()
data = resp.json()

# Extract titles
titles = [
    item.get("highlight", {}).get("title", "")
    for item in data.get("newsResults", [])
]

# Prepare stopwords
stop_words = set(stopwords.words('english'))

# Collect words
words = []
for title in titles:
    for word in re.findall(r'\w+', title.lower()):
        if word not in stop_words and len(word) > 2:
            words.append(word)

# Count frequency
counter = Counter(words)
most_common = counter.most_common(20)

# Handle empty case
if not most_common:
    print("No meaningful words.")
else:
    labels, counts = zip(*most_common)
    plt.figure(figsize=(12, 6))
    plt.bar(labels, counts, color='skyblue')
    plt.xticks(rotation=45, ha='right')
    plt.title("Top 20 meaningful words in news headlines")
    plt.ylabel("Frequency")
    plt.tight_layout()
    plt.show()
For deeper insight, upgrade from single words (unigrams) to bigrams (e.g., “Artificial Intelligence” instead of “Artificial” and “Intelligence”).
Sentiment Analysis with VADER
VADER (Valence Aware Dictionary and sEntiment Reasoner) is a rule-based model specifically optimized for social media and short headlines. It requires less computational power than LLMs while remaining effective for directional sentiment (Positive/Negative).
Logic:
- Compound >= 0.05: Positive
- Compound <= -0.05: Negative
- Else: Neutral
Short text may produce false positives/negatives, especially for headlines with numbers or factual statements without emotional tone.
import requests
import json
from nltk.sentiment.vader import SentimentIntensityAnalyzer
import nltk

# Download VADER lexicon for sentiment analysis
nltk.download('vader_lexicon')

API_KEY = "HASDATA-API-KEY"

# Parameters for Google News API request
params_raw = {
    "q": "",  # optional search query
    "gl": "us",  # geographic location
    "hl": "en",  # language
    "topicToken": "CAAqJggKIiBDQkFTRWdvSUwyMHZNREpxYW5RU0FtVnVHZ0pWVXlnQVAB",
    "sectionToken": "",
    "publicationToken": "",
    "storyToken": "",
    "so": ""
}

# Remove empty parameters
params = {k: v for k, v in params_raw.items() if v}

news_url = "https://api.hasdata.com/scrape/google/news"
news_headers = {"Content-Type": "application/json", "x-api-key": API_KEY}

# Fetch news data
resp = requests.get(news_url, params=params, headers=news_headers)
resp.raise_for_status()
data = resp.json()

# Initialize VADER sentiment analyzer
sid = SentimentIntensityAnalyzer()

# Prepare containers for sentiment groups
grouped_news = {"positive": [], "neutral": [], "negative": []}

# Analyze sentiment for each news item
for item in data.get("newsResults", []):
    highlight = item.get("highlight", {})
    text_to_analyze = highlight.get("title", "") + " " + highlight.get("snippet", "")

    score = sid.polarity_scores(text_to_analyze)
    news_item = {
        "title": highlight.get("title"),
        "link": highlight.get("link"),
        "snippet": highlight.get("snippet"),
        "source_name": highlight.get("source", {}).get("name"),
        "date": highlight.get("date"),
        "thumbnail": highlight.get("thumbnail")
    }

    # Classify news item based on compound score
    if score['compound'] >= 0.05:
        grouped_news["positive"].append(news_item)
    elif score['compound'] <= -0.05:
        grouped_news["negative"].append(news_item)
    else:
        grouped_news["neutral"].append(news_item)

# Save sentiment-classified news to JSON
with open("news_sentiment.json", "w", encoding="utf-8") as f:
    json.dump(grouped_news, f, ensure_ascii=False, indent=2)
VADER handles emotional tone but may struggle with financial nuance. A headline like “Profits fell by 20%” might be rated neutral if the dictionary lacks context for specific economic terms. For high-precision financial sentiment, consider fine-tuning a BERT model.
Legal & Ethical Compliance
Metadata is one thing, article bodies are another. Headlines, timestamps, and factual snippets are generally treated as public information and are safe to index for analytics. The full body text of an article is the publisher’s intellectual property. Teams routinely feed collected text into internal sentiment models, summaries, and trend dashboards, and that practice is widespread, but whether it qualifies as fair use depends on the jurisdiction and the specific case, so treat it as a question for counsel rather than a settled default. Republishing full articles on your own public site without a license is a copyright violation regardless of jurisdiction.
Request rates matter independently of copyright. A scraper that hammers a publisher’s servers creates problems no license covers, so keep crawling polite whichever method you use. Routing collection through HasData moves the rate limiting and header management to the service side.
Disclaimer: This guide is for informational purposes only and does not constitute legal advice. Data scraping laws (like GDPR in Europe or CFAA in the US) vary by region. Always consult with legal counsel regarding your specific use case.
Final Thoughts
A Google News scraper is three decisions, and this guide measured all of them. RSS feeds are structured and reliable within their 100-item ceiling. Scraping tbm=nws results reaches keyword coverage the feeds miss, at the price of proxies and upkeep when done directly. The News API returns the deepest feeds with the parsing already done. The comparison table above holds the measured differences, so the choice can rest on numbers rather than habit.
If you need to collect large volumes of news, the Google News API delivers the data in a structured format ready for analysis and integration into your workflow.