//button[contains(., 'Add to cart')] is the XPath text-matching form to reach for first. We ran six expression variants against 42 visible-text targets on 15 live retail pages, and the dot-based forms got the element in 95-98% of cases while the text()-based forms stopped at 67-69%. The short answer to text matching fits in a paragraph. This guide covers the rest, from why text() breaks through exact matching, case handling, and combining text with attributes, to the same expressions in Selenium, Scrapy, and Playwright.
All examples below run against this product card, which reproduces the three failure causes our measurement found on real pages (a button whose label shares the element with an icon span, a price with a non-breaking space, and a heading with whitespace around it), plus a deals link with an apostrophe for the quoting examples:
<div class="card">
<h3>
Aurora 14 Laptop
</h3>
<p class="price">1 299 USD</p>
<button type="submit">
<span class="icon"></span>
Add to cart
</button>
<a href="/aurora-14">Add to compare</a>
<a href="/deals">Don't miss today's deal</a>
</div>Copy it into a local file and every expression below can be replayed with lxml or a browser console.
contains(.) Against contains(text())
The two forms look interchangeable and behave differently on any element with children. text() returns the element’s own text nodes, and in XPath 1.0 (the version browsers, lxml, and Selenium evaluate) a string function applied to that node-set takes only the first node. The button above has two text nodes, the whitespace before the span and the label after it, so contains(text(), ...) tests the whitespace and fails:
//button[text()='Add to cart']
//button[contains(text(), 'Add to cart')]
Both return nothing on the card, though for different reasons. Equality against a node-set is existential in XPath 1.0, it tests every text node rather than the first, and the button still fails because no single text node equals the label once the padding around it counts. The dot means “this element’s entire text content, children included”, which is also what a person sees on the page and copies:
//button[contains(., 'Add to cart')]That returns the button. On our live-page sample this one difference separated 98% from 69% survival, because splitting a label with an icon, a highlight, or a formatting span is how modern markup is written.
Every ancestor of a match also contains its text, so the unanchored wildcard //*[contains(., 'Add to cart')] returns html, body, the card, and the button. Anchor the expression to a tag, as above, or pick the innermost match. The wildcard form is still useful when the tag is unknown but an attribute pins the element down, and //*[@type='submit'][contains(., 'Add to cart')] returns only the button.
Exact Text Matches Without Surprises
Exact equality against text() fails on invisible whitespace, which the card’s heading demonstrates. Its text node carries a newline and indentation on both sides:
//h3[text()='Aurora 14 Laptop']That returns nothing. normalize-space() trims the edges and collapses inner whitespace runs to single spaces, which makes the equals comparison behave the way it reads:
//h3[normalize-space(text())='Aurora 14 Laptop']That returns the heading. The same function on the dot, //button[normalize-space(.)='Add to cart'], is the exact-match counterpart of contains(.) and passed 95% of our live cases. Use it when a substring match is too loose, for example when “Add to cart” must not also match “Add to cart and checkout”.
Non-breaking spaces survive normalize-space(), and they show up in prices more than anywhere else. The card’s price carries U+00A0 between 1 and 299, so a filter typed with a regular space finds nothing:
//p[contains(text(), '1 299')]Zero matches, while the same expression with a literal non-breaking space between 1 and 299 returns the price. When a copied string stops matching, paste the page text into a hex viewer before doubting the XPath, or match a shorter fragment that skips the gap, like contains(., '299 USD').
Partial Matches and Case Handling
starts-with() works on both forms of text access and combines with normalize-space() when leading whitespace is in play:
//a[starts-with(normalize-space(.), 'Add')]On the card that returns the compare link. ends-with() is XPath 2.0 and does not exist in browsers, lxml, or Selenium, so the 1.0 workaround compares the tail with substring(normalize-space(.), string-length(normalize-space(.)) - 3) = 'cart', where the subtracted 3 is the suffix length minus one. The normalize-space() here is not optional. The card’s own button padding breaks the bare version, the same whitespace trap from the exact-match section.
XPath 1.0 string literals have no escape character. A label with an apostrophe still fits a double-quoted literal, and //a[contains(., "Don't miss")] returns the card’s deals link. When the expression itself is written inside a double-quoted string in Python or Java, or the text carries both quote kinds, concat() splices the quote in:
//a[contains(., concat("Don", "'", "t miss"))]That returns the same link.
Case-insensitive matching in 1.0 goes through translate(), which maps characters one to one:
//*[contains(translate(., 'ABCDEFGHIJKLMNOPQRSTUVWXYZ', 'abcdefghijklmnopqrstuvwxyz'), 'aurora')]On the card this returns four elements, html, body, the card div, and the heading, the unanchored-dot habit in action. Anchor it (//h3[contains(translate(...), 'aurora')]) and it returns only the heading. lower-case() is 2.0-only, same as ends-with(), and translate() covers ASCII only, so accented characters need their own mapping pairs.
Combining Text with Attributes, Tags, and Axes
Text conditions chain with attribute conditions through and, which is how one expression pins down an element that neither condition identifies alone:
//a[contains(., 'Add') and contains(@href, 'aurora')]Matching across several tags in one query takes a self:: union, which keeps the anchor while widening it:
//*[self::a or self::button][contains(., 'Add')]On the card that returns exactly the button and the link. Exclusion is not() wrapped around any of the same conditions:
//button[contains(., 'Add') and not(contains(., 'compare'))]And once text has located an anchor element, axes walk from it to the data that carries no usable text of its own. The price has no unique label, but the heading next to it does:
//h3[contains(., 'Aurora')]/following-sibling::p[@class='price']That returns the price paragraph. The sibling axes are a topic of their own, and the preceding-sibling answer covers the backward direction.
Which XPath Forms Survive on Real Pages
On 15 live retail homepages (Walmart, Target, Nike, Sephora, Newegg, and ten more from the same tier), contains(.) found 41 of 42 elements by their visible text, and no text()-based form got past 29. We auto-picked 42 visible-text targets, links, buttons, and headings with 4-40 characters of text, took each element’s text content as the DOM serializes it, and checked which of six expressions finds the element by that text in the raw DOM. T in the table stands for that text.
| Expression form | Found the element | Share |
|---|---|---|
//tag[contains(., 'T')] | 41 of 42 | 98% |
//tag[normalize-space(.)='T'] | 40 of 42 | 95% |
//tag[normalize-space(text())='T'] | 29 of 42 | 69% |
//tag[contains(text(), 'T')] | 29 of 42 | 69% |
//*[contains(text(), 'T')] | 29 of 42 | 69% |
//tag[text()='T'] | 28 of 42 | 67% |
The contains(text()) forms failed the same 13 cases, and exact text() equality lost one more to whitespace alone. Among the 14 labels the exact form missed the causes overlap, and two of the labels have more than one:
| Failure cause on the live pages | Occurrences |
|---|---|
Child elements split the text (icon or styling span inside) | 13 |
| Leading or trailing whitespace in the text node | 3 |
| Non-breaking space inside the visible text | 2 |
The one label that beat every form, contains(.) included, is Chewy’s “USA Menu” button, which combines a child split, a non-breaking space, and edge whitespace in a single element. For a label that mangled, text matching is the wrong tool, and the fallback is an attribute filter or an axis walk from a nearby anchor, like the sibling step in the combining section.
The gap is visible at a glance when the six forms sit side by side:
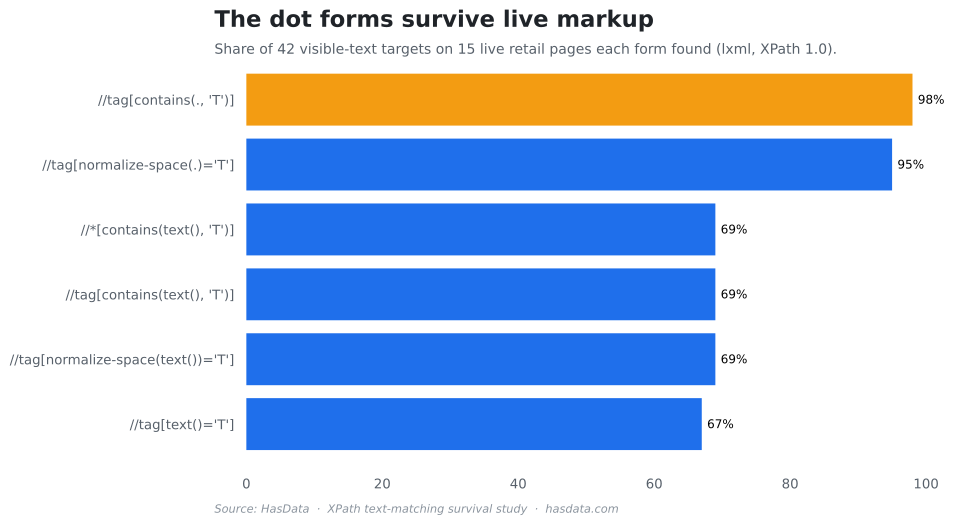
Write contains(.) or normalize-space(.) anchored to a tag by default, and reserve text() for markup you control or have inspected, because on retail-grade pages one label in three has something inside it.
The Same Expressions in Selenium, Scrapy, and Playwright
The expressions transfer as-is, and only the calling convention changes. In Selenium, text-based XPath is the standard way to find an element that has no stable id or class:
from selenium.webdriver.common.by import By

button = driver.find_element(By.XPATH, "//button[contains(., 'Add to cart')]")
button.click()
Scrapy evaluates the same string through its selectors, and lxml under it has the same XPath 1.0 rules as this whole guide:
price = response.xpath(
    "//h3[contains(., 'Aurora')]/following-sibling::p[@class='price']/text()"
).get()
Playwright accepts XPath in its locator syntax with the xpath= prefix, though its own get_by_text() covers the plain cases without XPath at all:
page.locator("xpath=//button[contains(., 'Add to cart')]").click()Whether XPath beats CSS for a given job is a separate decision, and the XPath in Selenium guide goes deeper on axes and functions in that stack.
Conclusion
Text matching in XPath is two decisions, the access form and the comparison. Take the dot over text() unless you have inspected the markup, take normalize-space() whenever equality is involved, anchor every dot expression to a tag, and check for non-breaking spaces and whitespace padding before blaming the expression. The demo card above reproduces all of it, so testing a new expression against it takes less time than reading a wrong answer.