The fastest way to scrape emails from a website is an API call with extractEmails enabled, and a plain regex over raw HTML also works, though in our 100-page test 45% of its matches were not email addresses at all. This guide covers both, plus obfuscated addresses, no-code tools, and the verification step that makes a scraped list safe to send to. I’ll start with cases where you already have a list of sites you want to scrape, and later I’ll touch on how to expand beyond that list using Google Search or Google Maps.
Email Scraping with Python
So, if you already have a list of websites and just need to scrape all available emails from them, the easiest way is to use an API that supports email extraction. We are using HasData’s web scraping API for this.
Let’s jump straight into the code for those who don’t care about the details and just want something that works:
import requests
import json
import csv


api_key = "YOUR-API-KEY"
headers = {
    'Content-Type': 'application/json',
    'x-api-key': api_key
}


results = []


with open("urls.txt", "r", encoding="utf-8") as file:
    urls = [line.strip() for line in file if line.strip()]


for url in urls:
    payload = json.dumps({
        "url": url,
        "proxyType": "datacenter",
        "proxyCountry": "US",
        "jsRendering": True,
        "extractEmails": True,
    })


    try:
        response = requests.post("https://api.hasdata.com/scrape/web", headers=headers, data=payload)
        response.raise_for_status()
        data = response.json()
        emails = data.get("emails", [])


        results.append({
            "url": url,
            "emails": emails
        })


    except Exception as e:
        results.append({
            "url": url,
            "emails": []
        })


with open("results.json", "w", encoding="utf-8") as json_file:
    json.dump(results, json_file, ensure_ascii=False, indent=2)


with open("results.csv", "w", newline="", encoding="utf-8") as csv_file:
    writer = csv.writer(csv_file)
    writer.writerow(["url", "email"])
    for result in results:
        for email in result["emails"]:
            writer.writerow([result["url"], email])
Replace the API key with your own HasData key, which you can get after signing up. Also, make sure you have a file called “urls.txt” in the same folder as the script. This file should have the list of domains you want to scrape.
The whole script works like this:
- Get a list of sites from urls.txt file.
- Loop through the list.
- For each site, call the API, parse the response, and pull out emails.
- After the loop, save everything as JSON and CSV files.
Scrape Emails from a Website using AI
The same web scraping API can get not just emails, but any other contact info, like phone numbers. The API can use an LLM to extract data from the page based on a natural language description. Right now, after running the script, you get JSON and CSV files with emails like this:

Let’s add an AI extraction rule to the API request:
    payload = json.dumps({
        "url": url,
        "proxyType": "datacenter",
        "proxyCountry": "US",
        "jsRendering": True,
        "extractEmails": True,
        "aiExtractRules": {
            "address": {"description": "Physical address", "type": "string"},
            "phone": {"description": "Phone number", "type": "string"},
            "email": {"description": "Email addresses", "type": "string"},
            "companyName": {"description": "Company name", "type": "string"}
        }
    })
And handle the AI’s response when we get the JSON results:
        data = response.json()


        emails_list = data.get("emails", [])
        ai_resp = data.get("aiResponse", {})


        company = ai_resp.get("companyName", "-")
        address = ai_resp.get("address", "-")
        phone = ai_resp.get("phone", "-")
        email_ai = ai_resp.get("email", "")
Since we’re getting emails both from the standard API call and from the AI, we’ll combine them to avoid missing anything, just make sure to remove duplicates:
        all_emails = set(emails_list)
        if email_ai:
            all_emails.add(email_ai)


        email_combined = ", ".join(sorted(all_emails)) if all_emails else ""
Also, we’ll need to change the CSV saving part a bit because the column names and content are hardcoded:
with open("results_ai.csv", "w", newline="", encoding="utf-8") as csv_file:
    writer = csv.writer(csv_file)
    writer.writerow(["url", "company", "address", "phone", "emails"])
    for result in results:
        writer.writerow([
            result["url"],
            result["company"],
            result["address"],
            result["phone"],
            result["emails"]
        ])
The rest of the code stays the same, but here’s the full updated version just in case:
import requests
import json
import csv


api_key = "YOUR-API-KEY"


headers = {
    'Content-Type': 'application/json',
    'x-api-key': api_key
}


results = []


with open("urls.txt", "r", encoding="utf-8") as file:
    urls = [line.strip() for line in file if line.strip()]


for url in urls:
    payload = json.dumps({
        "url": url,
        "proxyType": "datacenter",
        "proxyCountry": "US",
        "jsRendering": True,
        "extractEmails": True,
        "aiExtractRules": {
            "address": {"description": "Physical address", "type": "string"},
            "phone": {"description": "Phone number", "type": "string"},
            "email": {"description": "Email addresses", "type": "string"},
            "companyName": {"description": "Company name", "type": "string"}
        }
    })


    try:
        response = requests.post("https://api.hasdata.com/scrape/web", headers=headers, data=payload)
        response.raise_for_status()
        data = response.json()


        emails_list = data.get("emails", [])
        ai_resp = data.get("aiResponse", {})


        company = ai_resp.get("companyName", "-")
        address = ai_resp.get("address", "-")
        phone = ai_resp.get("phone", "-")
        email_ai = ai_resp.get("email", "")


        all_emails = set(emails_list)
        if email_ai:
            all_emails.add(email_ai)


        email_combined = ", ".join(sorted(all_emails)) if all_emails else ""


        results.append({
            "url": url,
            "company": company,
            "address": address,
            "phone": phone,
            "emails": email_combined
        })


    except Exception as e:
        results.append({
            "url": url,
            "company": "-",
            "address": "-",
            "phone": "-",
            "emails": ""
        })


with open("results_ai.json", "w", encoding="utf-8") as json_file:
    json.dump(results, json_file, ensure_ascii=False, indent=2)


with open("results_ai.csv", "w", newline="", encoding="utf-8") as csv_file:
    writer = csv.writer(csv_file)
    writer.writerow(["url", "company", "address", "phone", "emails"])
    for result in results:
        writer.writerow([
            result["url"],
            result["company"],
            result["address"],
            result["phone"],
            result["emails"]
        ])
Here’s an example of the kind of data you can extract:

If you need to extract more data later, just add the description to aiExtractRules, and the model will handle it automatically.
Extracting Emails with Regex in Python
If you don’t want to use an API, you can try a more hardcore approach and scrape emails yourself without any third-party tools.
The script reads the same urls.txt, fetches each page with requests, runs a regular expression over the HTML, and saves every match:
import requests
import re
import csv


found_emails = set()
output_file = "found_emails.csv"
file_path = "urls.txt"

headers = {
    "User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 "
                  "(KHTML, like Gecko) Chrome/139.0.0.0 Safari/537.36",
    "Accept-Language": "en-US,en;q=0.9",
}

with open(file_path, "r", encoding="utf-8") as file:
    websites = [line.strip() for line in file if line.strip()]


email_pattern = r"[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,}"
for website in websites:
    try:
        response = requests.get(website, timeout=10, headers=headers)
    except requests.RequestException as e:
        print(f"[error] {website}: {e}")
        continue
    if response.status_code == 200:
        emails = re.findall(email_pattern, response.text)
        for email in emails:
            found_emails.add((website, email))
    else:
        print(f"[{response.status_code}] {website}")


with open(output_file, "w", newline="", encoding="utf-8") as csv_file:
    writer = csv.writer(csv_file)
    writer.writerow(["Website", "Email"])
    for website, email in found_emails:
        writer.writerow([website, email])
The regex does the real work here. There’s an official standard for email formats called RFC 5322 (Internet Message Format), and its full pattern is so detailed that nobody uses it in practice. The simpler pattern in the script catches nearly every address that actually appears on pages. One character matters, though. A widely copied variant of this pattern ends its TLD part with [A-Z|a-z]{2,}, and the | inside a character class is not “or”, it is a literal pipe character. In the 100-page run below, that variant matched strings like DotComProd@sephora.com|canadaComplianceReportSubject from a page’s embedded config. The script above uses the correct [A-Za-z]{2,} form.
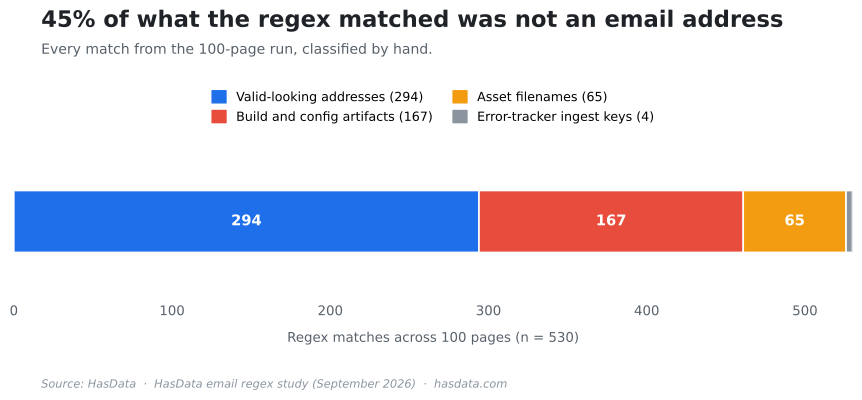
We ran this regex over 100 live pages (homepages and contact pages of well-known retail, news, and tech sites) to see what the approach actually returns. The run fetched with the same browser headers and used the widespread [A-Z|a-z] variant, which is how the pipe bug above was caught in the same pass, and its 3 pipe-glued matches are counted in the artifact classes. Match by match:
| Match class | Count |
|---|---|
| Valid-looking addresses | 294 |
Build and config artifacts (hash-suffixed bundle filenames like commerce@2x-957a6914…png, pipe-glued config strings) | 167 |
Asset filenames (logo@2x.png, icon@3x.svg) | 65 |
Error-tracker ingest keys (hex-string@sentry.io) | 4 |
Only 49 of the 100 pages produced any match at all, and 37 produced at least one valid-looking address, because large sites publish contact forms rather than addresses. Of the 530 total matches, 236 (45%) were not email addresses. Filtering out matches that end in a file extension and running the regex over visible text instead of raw HTML removes most of that junk. The pattern also swallows neighboring encoding, so some matches come back with characters glued to the local part, either a percent-encoded space as in %20feedback@slate.com or a JSON escape as in u003esupport@goat.com. Those are not junk. Running urllib.parse.unquote over each match and stripping any leading escape recovers the real address, and in our sampled addresses all three affected matches decoded cleanly. Normalize before you validate, because % is a legal character in a local part, so %20feedback@slate.com passes a syntax check exactly as it stands.
Bot protection is the other limit of this approach. To improve success on protected sites, you need to add a headless browser instead of just requests, then proxies, and the setup keeps growing from there. A scraping API with JavaScript rendering and its own proxy pool, like HasData’s, replaces that whole stack with one request.
Scraping Obfuscated Email Addresses
Many sites publish an address in a form the plain regex never sees. Ordinary mailto: links are still the easy case, because the address is right in the raw HTML (14 pages in our 100-page run carried them, and the regex matched on 13). In the same run, one page served its addresses through Cloudflare’s email protection and one spelled an address out in words. Those are the forms that escape text extraction:
- Spelled-out addresses, like
info [at] example [dot] comorsales(at)example(dot)com. The page text is readable, the regex finds nothing. - Cloudflare email protection. The HTML contains
<a data-cfemail="...">[email protected]</a>, and a script decodes the hex string in the browser. The raw HTML has no address at all. - JavaScript assembly. The page builds the address at runtime from parts (
user + "@" + domain), sometimes straight into amailto:href. Only a rendered DOM contains it. - Images. The address is a picture. Nothing text-based finds it, and OCR is the only programmatic way in.
The first two decode with a few lines. Spelled-out forms normalize back into @ and . before the regex runs, and the data-cfemail value is a one-byte XOR with its first byte as the key:
import re

def normalize_spelled(text):
    text = re.sub(r"\s*[\[(]\s*at\s*[\])]\s*", "@", text, flags=re.I)
    return re.sub(r"\s*[\[(]\s*dot\s*[\])]\s*", ".", text, flags=re.I)

def decode_cfemail(hex_string):
    key = int(hex_string[:2], 16)
    return bytes(
        int(hex_string[i:i + 2], 16) ^ key
        for i in range(2, len(hex_string), 2)
    ).decode("utf-8")

print(re.findall(r"[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,}",
                 normalize_spelled("write to info [at] example [dot] com")))
print(decode_cfemail("422b2c242d02273a232f322e276c212d2f"))
Both calls return info@example.com. JavaScript-assembled addresses need the rendered DOM, so fetch with jsRendering enabled (or a headless browser) and run extraction on the result instead of the raw response. The spelled-out case is also exactly what the AI extraction from the earlier section handles without any normalization code, since the model reads the rendered text the way a person does and returns the assembled address as a plain string.
Use a Contact Scraper to Get Emails Without Coding
HasData’s Email Scraper is a website email scraper that pulls addresses and other contact details from a list of sites without any code. All you need is the list itself:

After that, you can download the data as a CSV, JSON, or XLSX. Here’s an example of the data that you’ll get:
[
    {
        "url": "https://thecreganteam.com/",
        "xcom": [],
        "clutch": [],
        "emails": [
            "john.cregan@sothebys.realty.com"
        ],
        "dribbble": [],
        "facebook": [
            "https://www.facebook.com/thecreganteam"
        ],
        "linkedin": [
            "https://www.linkedin.com/in/john-cregan-218a608/"
        ],
        "instagram": [
            "https://www.instagram.com/lisa_and_john_palmbeach/"
        ],
        "phoneNumbers": [
            "+1.847.651.7210"
        ]
    },
  ...
]
This works if you need the data quickly and want every kind of contact info the page exposes, beyond emails alone.
Using Streamlit for Email Scraping
This last option is for those who not only need to scrape contact data from a site but also want help finding the right sites to begin with, whether through Google Maps, search results, or both. Or maybe the other methods didn’t work, and you just want something that works out of the box.
For that, we built an easy-to-use Email Scraping Tool.

You can pick one of three methods:
- List of URLs. Use this if you already have a list of sites to pull emails from.
- Google SERP Keywords. Use this if you want to search sites by keyword and then scrape emails and contact info from them.
- Google Maps Keywords. Use this if you want to search for places on Google Maps and then retrieve emails and contact information from those locations. If that’s not enough, we wrote a separate guide on scraping emails from Google Maps.
To run the scraper, enter your HasData API key and either a list of websites or keywords, depending on the method you choose. Then, run the scraper:
When it’s done, you can copy the data table (or part of it) or download the data as JSON or CSV.
Browser Extensions and Desktop Crawlers Compared
A few other “no-API” roads still get taken, like browser add-ons and old-school desktop crawlers. They both have their moments, but each comes with strings attached.
Browser extensions are the easiest win: most are free, live right in Chrome/Edge, and need zero setup. You click the icon, and any visible addresses on the current page pop out.
That simplicity is also a trap. You’re scraping in half-manual mode through your own browser tab. And at scale, this feels like panning for gold with a teaspoon, one page at a time, so pulling even a thousand emails is really difficult and time-consuming.
Stand-alone desktop crawlers feel more “pro.” You point them at a URL list, hit Start, and they process pages without requiring code. It’s nice until you realize they run from a single residential IP, hit CAPTCHAs after a few hundred requests, and need constant rule tweaks each time a site changes its markup.
Cross-platform support is unreliable, licenses can add up, and scaling requires additional hardware or renting virtual private servers (VPSs). In practice, desktop crawlers are suitable for small projects, but when you need reliable throughput and compliance safeguards, you’ll likely switch to a service that manages proxies, rendering, and retries for you.
Verifying Scraped Emails Before You Send
Every scraped list carries addresses that will never deliver mail. Some are placeholders (address@email.com showed up in our own run), some belong to employees who left, and some are spam traps. Sending to an unverified list raises the bounce rate, and mailbox providers score the sending domain on exactly that, so one bad batch damages deliverability for everything you send afterward. Verification runs in stages, each cheaper than the next one, and syntax filtering already happened if the regex is strict.
MX Lookup
An MX lookup checks that the domain can receive mail at all, for the cost of one DNS query:
import dns.resolver  # pip install dnspython

def has_mx(domain):
    try:
        answers = dns.resolver.resolve(domain, "MX", lifetime=8)
        return sorted(str(r.exchange) for r in answers)
    except (dns.resolver.NXDOMAIN, dns.resolver.NoAnswer,
            dns.resolver.NoNameservers, dns.resolver.LifetimeTimeout):
        return []

print(has_mx("hasdata.com"))
The lookup removes dead domains and typos before anything touches SMTP. Across a sample of the addresses our regex run collected, 40 of 44 unique domains had MX records, and mail to the other four had nowhere to go.
Put end to end, the two runs show where a scraped list loses its volume.

Fetching is the cheap part of that chain. Nearly every step after it throws something away, which is why a list is worth verifying before it is worth sending to.
SMTP Probe Without Sending
An SMTP probe checks whether a specific mailbox exists without sending an email. It connects to the MX host on port 25, sends MAIL FROM and RCPT TO, and reads whether the server accepts the recipient. Most residential and office networks cannot run it at all, since providers block outbound port 25 (from our network, connections to Google’s MX hosts timed out). And many servers answer 250 OK for any mailbox (catch-all) or defer unknown senders (greylisting), so the probe’s answer is not proof.
Verification Services
Verification services (ZeroBounce, NeverBounce, Kickbox, and similar) run those probes from established mail infrastructure, layer catch-all and spam-trap detection on top, and return a per-address deliverability verdict. For a list that took an hour to scrape, the verification step is what makes it safe to actually use.
Legal and Ethical Considerations of Email Scraping
Before scraping or emailing, ensure you have a lawful basis for data processing. Under GDPR and CCPA, this typically means obtaining explicit consent or demonstrating “legitimate interest.” In the U.S., CAN-SPAM requires clear subject lines, a physical address, and an easy opt-out option in each email.
Violations can lead to hefty fines. Mass-harvesting emails can also breach site terms, damage sender reputation, and be unwelcome. Collect only necessary contact information, respect opt-outs, and use the data responsibly.
When to Use Each Email Scraping Method (Quick Guide)
Let’s wrap this up with a quick guide on when to use each email scraping method we covered:
| Method | Code Needed | Setup Difficulty | Extracts | Best For |
|---|---|---|---|---|
| Regex Script (Python) | Yes | Medium | Emails only | Devs scraping basic pages |
| HasData API | Yes | Easy | Emails + address + phone | Devs who want scale and accuracy |
| Email Scraper | No | Very Easy | Emails + phones + social links | Non-coders who already have a URL list |
| Streamlit Tool | No | Easy | Emails + company + social links | Non-coders who also need to find sites |
| Browser Extension | No | Very Easy | Visible emails only | Beginners doing manual small-scale work |
| Desktop Crawler | No | Medium/Hard | Emails (limited at scale) | Offline batch scraping (limited volume) |
That’s it! Each of these methods has its own section above, so you can jump back to whichever one fits your needs best.